TL;DR: A lead qualification agent reads inbound leads, checks them against what you already know, scores them against your ideal customer profile, and routes the ones worth a human. The decision worth thinking about is not which tool to use but whether to build it in-house or pay for the build. Building wins when you already run automation tooling and can give it a month of attention; paying wins when the volume is already costing senior-team hours or when nobody internally will own it afterwards. This is the practical companion to our strategic primer on agentic workflows.
Contents
- What a lead qualification agent does
- The decision is build-vs-buy, not tool-vs-tool
- When building it yourself wins
- When paying for the build wins
- What it actually costs
- What breaks, and why it is not the part you expect
- What not to build first
- Canadian data residency note
- Key Takeaways
- FAQ
The agentic workflows guide covers the theory. This post covers the decision.
If your business gets inbound leads by email and someone on the team manually reads each one to decide whether it’s worth pursuing, an agent can take the first pass. It doesn’t replace judgment. It handles the triage so your judgment only kicks in on the leads that scored well.
What a lead qualification agent does
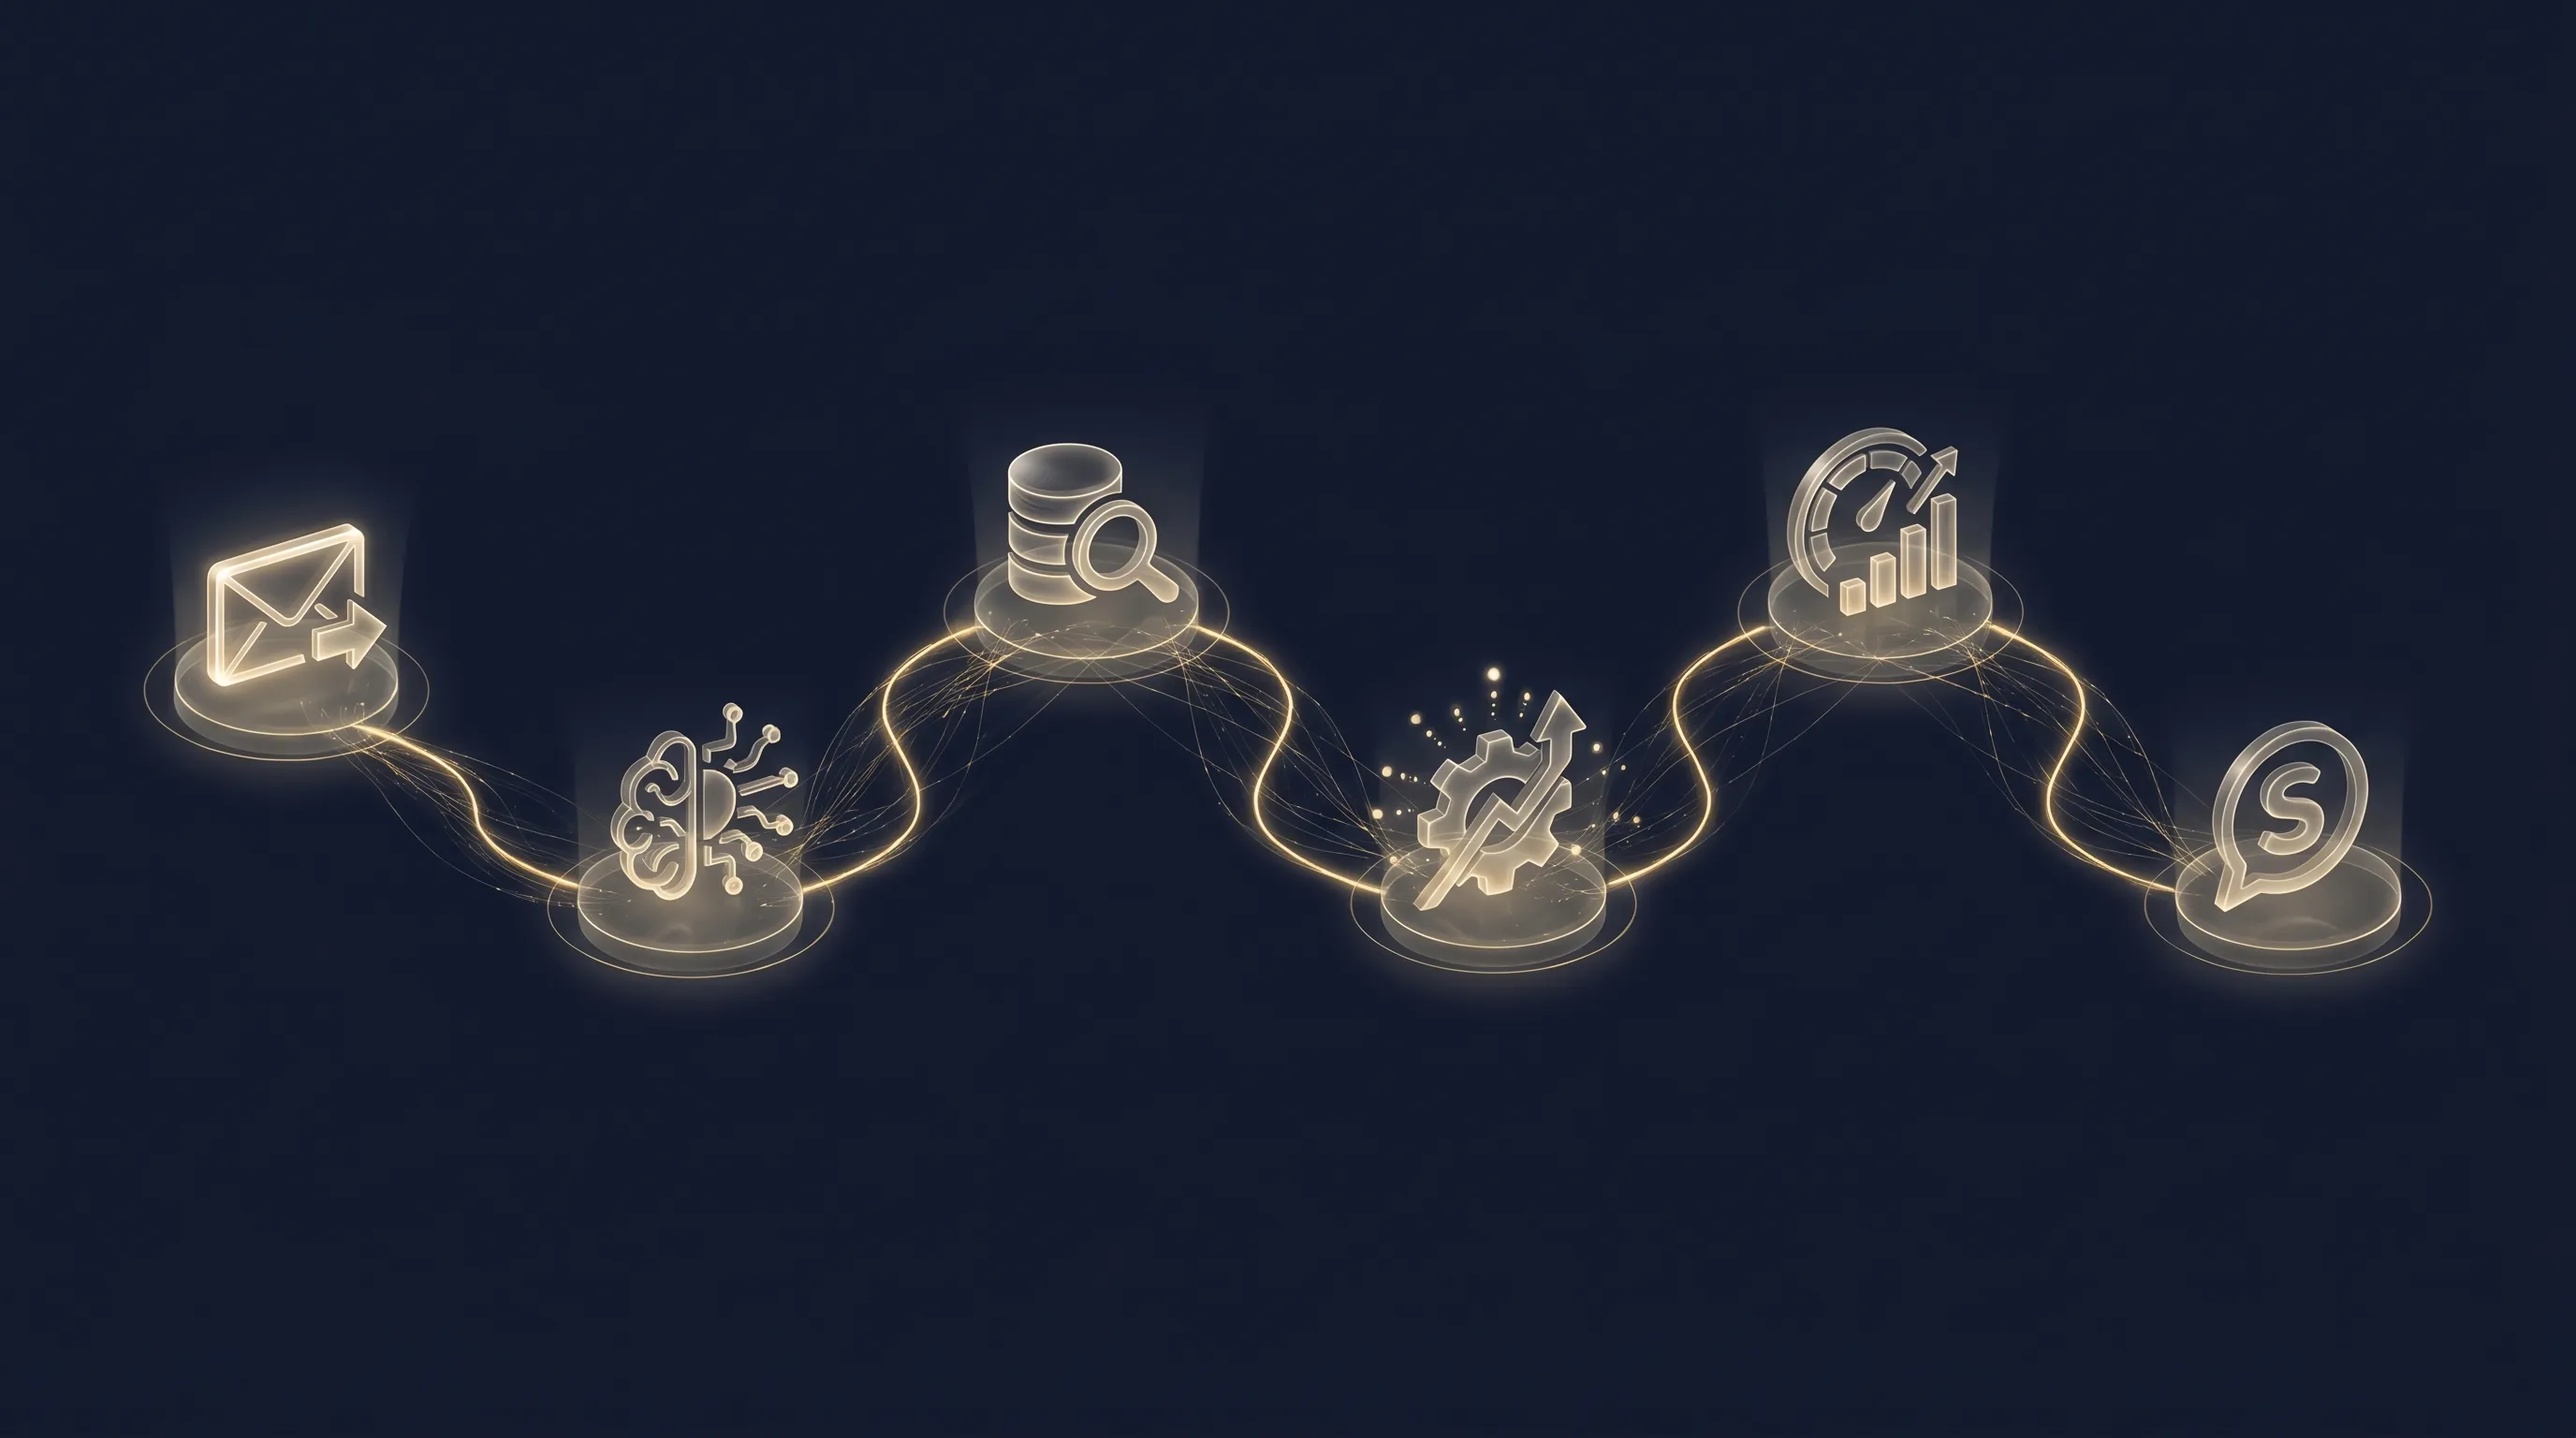
It reads a new inbound lead, pulls out the facts worth having in a structured form, checks whether you already have a relationship with that company, scores the lead against your ideal customer profile, and routes the result. Qualified leads reach a human with the context attached. Unqualified ones get logged rather than lost.
It replaces a task that takes a person three to seven minutes per lead and needs focused attention to do well. At a hundred leads a month that is most of a working day of senior-team time, spent on something where the first pass is mostly mechanical. It is one of the cleanest cases for AI agents at SMB scale, which is exactly why so many of these projects get started and then quietly abandoned.
What you should end up with is a scored record, a notification for the ones worth chasing, and a log of what the agent saw and decided. The log is not a nice-to-have. Without it you cannot tell a good score from a lucky one.
The decision is build-vs-buy, not tool-vs-tool
Most of the published writing on this topic is a tool comparison, and the tool is the least consequential choice you will make. The orchestration layer and the model are both commodities at this scale, and a competent build on any mainstream pairing will outperform a careless build on the best one.
The decision that determines whether the project works is who owns it. An agent that scores leads is a system that makes a judgment call hundreds of times a month on your behalf. Someone has to decide what good looks like, check whether the agent agrees, and adjust it when it does not. That is a standing responsibility, not a launch task, and it is the thing build-vs-buy is really about.
When building it yourself wins
You already run your own automation tooling. If there is a workflow platform in the business and someone who maintains it, the marginal cost of one more workflow is small and the knowledge stays in-house.
Your ideal customer profile is written down and stable. The scoring is only as good as the definition behind it. If you can already state in writing which leads matter and why, you have done the part that no vendor can do for you.
You can give the first month real attention. The scoring will be wrong often enough at the start that someone has to read the results by hand and adjust. If that person exists and has the time, building is the cheaper path and you end up understanding your own system.
The volume is low enough that mistakes are cheap. At modest volume a mis-routed lead is recoverable. That is a good environment to learn in.
When paying for the build wins
Lead volume is already costing senior-team hours. If the triage is eating time from people whose time is the constraint, the payback on getting it right quickly is larger than the saving from doing it slowly yourself.
The scoring has to survive a sales team. A score that the sales team does not trust gets ignored, and then the system is worse than nothing because it adds a step without removing one. Making scoring defensible is a design problem with a lot of prior art behind it, and prior art is the thing you are buying.
Nobody internally will own it after launch. This is the most common reason these projects fail, and it is rarely the reason given. If there is no named owner for the month after go-live, buying the build and the support is honest; building it yourself is just deferring the failure.
The data is sensitive or regulated. Where the data goes becomes a question you have to answer to someone else, and that is worth having done by people who have answered it before.
What it actually costs
At the volumes most SMBs see, the running cost lands in the tens of dollars a month, and hosting is usually a larger share of it than model usage. That number surprises people in both directions: it is far cheaper than the enterprise tooling sold for this job, and it is not the number that matters.
The cost that decides the project is attention. The first month needs someone reading the agent’s decisions against their own judgment and adjusting the definition behind the score. Budget that honestly and the running cost is a rounding error. Budget only the running cost and you will have a cheap system that nobody trusts.
The same arithmetic is what makes the build-vs-buy call concrete: compare the hours the triage currently consumes against the hours the first month of calibration will consume, not against the monthly bill.
What breaks, and why it is not the part you expect
The failures that matter here are not crashes. They are confident wrong answers, and they are the reason this is harder than it looks from a demo.
A failed lookup reads exactly like a negative result. When a check against your existing records comes back empty, there are two possible reasons: there is genuinely no prior relationship, or the check did not work. Those have opposite consequences and look identical, and a system that does not distinguish them will eventually route a long-standing customer as a cold lead.
A model’s confidence is not evidence. The output arrives in the same format and the same tone whether it is right or wrong. Anything downstream that treats a well-formed answer as a correct one inherits that problem, and the only real defence is checking a sample against human judgment on an ongoing basis.
Costs climb quietly. An automated system that retries on failure can do so for hours without telling anyone. Whoever builds it needs to have thought about limits before it runs unattended, not after the first bill.
Real inputs are messier than test inputs. Forwarded chains, signature blocks, auto-replies and marketing footers all arrive looking like leads. This is where most of the unglamorous work actually goes, and a build that was only ever tested on clean examples has not been tested.
If you are evaluating someone else’s build, these are the questions worth asking, and the answers tell you more than a feature list will. For the broader pattern of agents failing without announcing it, our production gotchas post covers the shape of the problem, and the agent-to-agent coordination post covers what happens when the failing step is one agent among several.
What not to build first
The next logical step after scoring is drafting a response for the sales rep. Don’t build that yet, whoever is building it.
You will not know what a good score looks like until a few hundred real leads have been through the system and someone has checked the results by hand. The definition behind the scoring will need adjustment. If a response generator is already bolted on, you are debugging that at the same time as the scoring, and you will not be able to tell which layer is wrong.
Ship the scoring and the routing. Let it run for a month. Check whether the leads it rated highly actually converted, and adjust the definition based on what you learn. Build the response layer on top of a scoring model you already trust.
The same restraint applies to edge cases. You will think of a dozen before launch and none of them will be the ones that appear. Ship a system that handles the common path well and iterate on real failures.
Canadian data residency note
If your leads include Canadian residents, you are processing personal information (names, email addresses, company details) through whichever model provider you choose. By default most of them process on US infrastructure. Under PIPEDA you need to understand where that data goes, who your subprocessors are, and how to respond to a deletion request.
Some providers offer Canadian data residency options under enterprise agreements. If you are processing meaningful volumes of Canadian personal data, confirm residency with your provider before going live, and document the data flows and your legal basis for processing before the workflow touches production data. This is a short conversation with your lawyer rather than a blocker, and what data sovereignty actually means sets out the distinction that matters here. Don’t skip it.
Key Takeaways
- The tool choice matters far less than who owns the system after launch. That is the real build-vs-buy question.
- Build it yourself when you already run automation tooling, your ideal customer profile is written down, and someone can give the first month genuine attention.
- Pay for the build when the triage is already costing senior-team hours, when the scoring has to be defensible to a sales team, or when nobody internally will own it.
- Running cost lands in the tens of dollars a month at SMB volumes. The cost that decides the project is the attention the first month needs.
- The failures that matter are silent and confident, not loud. A failed lookup that reads as a negative result is the classic one.
- Calibrate the scoring for a month before adding a response-generation layer. Sequence matters more than scope.
- Canadian businesses: map your data flows before go-live. PIPEDA applies as soon as the workflow touches personal information.
Need someone to build agents like this?
We design, build, and deploy custom AI agents on your infrastructure. Production-grade reliability, full code ownership, no vendor lock-in. See our AI Agent Development service for the operational details, or book a discovery call.
If you are weighing this up for your own business, the fastest first step is a conversation about your actual lead volume and what the triage is costing you today. Book a call and we will tell you honestly which side of the decision you are on.
Soli Deo Gloria
Frequently Asked Questions
Should I build a lead qualification agent myself or pay someone?
Build it yourself if you already run your own automation tooling, your ideal customer profile is written down and stable, and you can give the first month real attention. Pay for the build when lead volume is already costing senior-team hours, when the scoring has to be defensible to a sales team that will push back, or when nobody internally owns it after launch. The build is rarely the hard part; the calibration and the ownership are.
What does a lead qualification agent cost to run?
At the volumes most SMBs see, running cost lands in the tens of dollars a month, and hosting rather than model usage is usually the larger share. Treat that as the floor, not the budget. The cost that decides the project is attention in the first month, while the scoring is still wrong often enough to need checking by hand.
Do I need to know how to code?
Not necessarily. Visual workflow tools cover most of this without code, and the genuinely hard parts are not coding problems. Writing an ideal customer profile precise enough for a model to apply consistently, and deciding what the agent must never decide alone, are judgment problems that no tool removes.
What goes wrong most often?
Silent wrong answers rather than visible failures. A lookup that fails and gets read as "no existing relationship", a model response that is confidently wrong, or a cost that climbs quietly while you sleep. None of them throw an error. The question to ask of any build, your own or a vendor's, is what happens when a step fails rather than what happens when it works.
Is this PIPEDA-compliant for Canadian businesses?
It depends on your configuration. Most major model providers process on US infrastructure by default, so if your leads include Canadian residents you are passing personal information through a US-based subprocessor. Check whether your provider offers a Canadian or EU data residency option before wiring customer data through, and map your data flows and document your subprocessors before going live.